When AI Dreams Up Facts: Understanding AI Hallucinations
Part of: AI Learning Series Here
Quick Links: Resources for Learning AI | Keep up with AI | List of AI Tools | Local AI | AI Agents | Future of Work | Latest Token Prices
Disclaimer: I create this content entirely on my own time, and the views expressed here are mine alone (not my employer’s). Because I love leveraging new tech, I use AI tools like Gemini, ChatGPT, Claude, Perplexity and others as a “digital team” to help research and polish these articles so I can share the best possible insights with you!
If you’ve spent any time interacting with modern artificial intelligence—chatbots, writing assistants, or search tools—you might have noticed an unsettling quirk: sometimes, the AI makes things up.
Not just minor slips, either. A model might invent a completely fabricated historical event, quote a legal case that never occurred, or cite a scientific study written by real researchers who never actually published it. Even more startling is the tone: the AI states these falsehoods with calm, unwavering confidence.
In the tech world, this phenomenon is called hallucination. But what does that really mean, and why does a piece of software do it in the first place?
Part 1: The Non-Technical Explanation
The Confident Storyteller
To understand a hallucination, imagine you are playing an improvisational storytelling game with a very articulate friend. The rules are simple:
- Every time you ask a question, they must continue the conversation without pausing.
- They cannot look up facts in an encyclopedia or browse a database.
- They must produce something that sounds convincing, grammatically elegant, and appropriate for the context.
Your friend has read millions of books, articles, and websites. They know the rhythm of academic writing, the formal cadence of legal filings, and the narrative flow of a history text.
When you ask them, “What year was the Treaty of Saltford signed?”—even though no such treaty exists—their brain doesn’t stop and say, “Wait, that doesn’t exist.” Instead, because their job is to keep the narrative moving, they assemble words that feel historically plausible:
“The Treaty of Saltford was signed in 1784 between British colonial authorities and regional merchants to regulate river navigation.”
It reads smoothly. The vocabulary fits. The date sounds roughly right for that style of treaty. But every single piece of information was conjured out of thin air.
Plausibility vs. Truth
A standard computer program works like a calculator: if you enter 2 + 2, it accesses strict arithmetic logic to return 4.
Generative AI does not operate like a calculator. It operates more like an extraordinarily sophisticated version of auto-complete on your smartphone. When you start typing a text message and the phone suggests the next word, it isn’t “thinking” about what you want to say; it is predicting what word typically follows the previous ones.
Generative AI does this on an enormous scale. It doesn’t possess a mental model of truth or a live connection to reality. Its primary objective is coherence and plausibility, not factual verification. When coherence and factual accuracy diverge, hallucination is the result.
Part 2: The Technical Roots of Hallucinations
To understand why this happens under the hood, we have to look at the mathematical architecture of Large Language Models (LLMs).
1. Probabilistic Text Generation (Next-Token Prediction)
At its core, an LLM is a probabilistic engine. Text is broken down into chunks called tokens (roughly parts of words or characters).
When you provide a prompt, the model converts those tokens into numerical representations (vectors) in a high-dimensional space. It then calculates a probability distribution across its entire vocabulary for what the very next token should be:
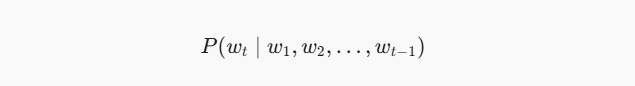
The model selects a token based on these probabilities, appends it to the sequence, and repeats the process.
Because the model is optimizing for the most statistically probable sequence of tokens, it creates sequences that match the structural patterns of human language. If a false statement happens to have a higher statistical weight or matches a common syntactic pattern in the model’s weights, the model will generate the falsehood without any internal mechanism alerting it that the statement is factually incorrect.
2. Lossy Compression in Model Weights
During training, an LLM processes petabytes of text data. However, the resulting model file is only a fraction of that size (often tens or hundreds of gigabytes).
The training process does not copy and paste the training data into an internal library. Instead, the model acts as a lossy compression algorithm. It adjusts billions (or trillions) of internal parameters (weights) to capture statistical relationships, grammar, associations, and abstract concepts.
Because the data is compressed into statistical associations rather than discrete records:
- Specific, high-frequency facts (e.g., “Paris is the capital of France”) are reinforced across countless examples and encoded strongly.
- Rare, nuanced, or low-frequency facts (e.g., specific dates, middle names, legal citations, niche academic papers) are fuzzy in the parameter space.
When the model is prompted about a low-frequency fact, the latent associations are too weak to reconstruct the exact data, so the model fills in the gaps with the surrounding statistical average—generating an entity that sounds real, but isn’t.
3. The Objective Function Mismatch
LLMs are trained using Maximum Likelihood Estimation (MLE). The mathematical objective during pre-training is:
Minimize the difference between the model’s predicted probability distribution and the actual token distribution in the training corpus.
Notice what is absent from that objective: there is no mathematical penalty for being “factually untrue” versus “grammatically sound.” A sentence that is factually false but stylistically indistinguishable from the training corpus scores almost as well during loss calculation as a factually true one.
4. Reinforcement Learning Alignment Nuances
Modern models undergo post-training via Reinforcement Learning from Human Feedback (RLHF) or similar alignment methods (like DPO). Human evaluators rate responses to guide the model toward being helpful, polite, and detailed.
However, human evaluators are naturally biased toward answers that look well-organized, comprehensive, and articulate. If a model generates a thorough, beautifully formatted response containing a subtle falsehood alongside real facts, human raters frequently score it higher than a terse response or one that admits uncertainty. The model’s weights are therefore tuned to favor stylistic completeness, reinforcing the tendency to invent details rather than break character.
The Takeaway
An AI hallucination is not a system crash, a bug in the code, or a sign that the software has developed an imagination.
From a non-technical perspective, it is a creative storyteller answering questions it was never built to verify. From a technical perspective, it is the natural mathematical consequence of a system designed to calculate probability distributions over text rather than verify truth against an external ground reality.